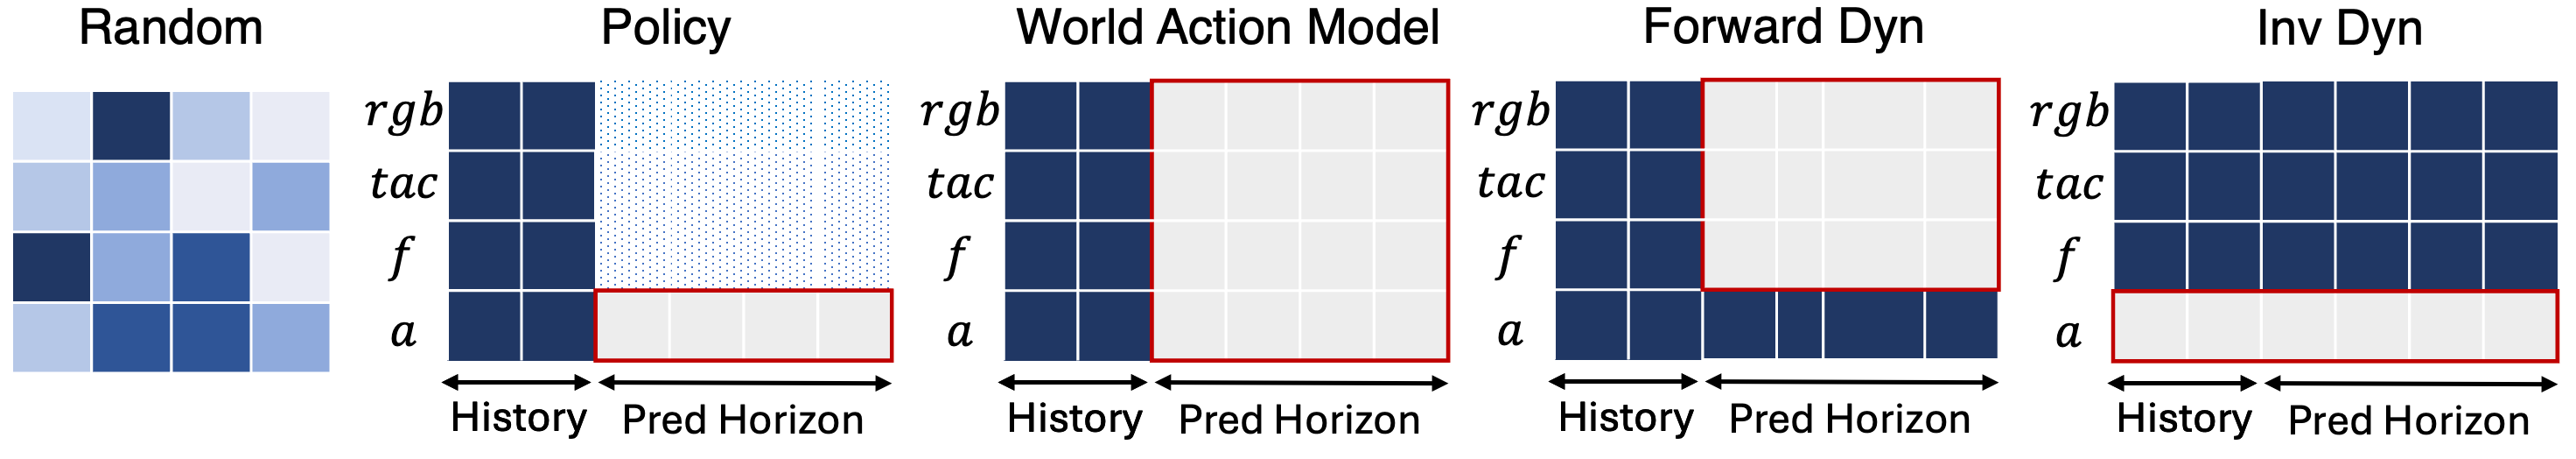
Recently, world-action models (WAMs) have emerged as a powerful framework for robot manipulation. By jointly modeling action generation and future observation prediction, WAMs can act and anticipate the outcomes of the actions. However, existing WAMs typically rely on frozen pretrained encoders trained with reconstruction, which may not produce representations well suited for robot control.
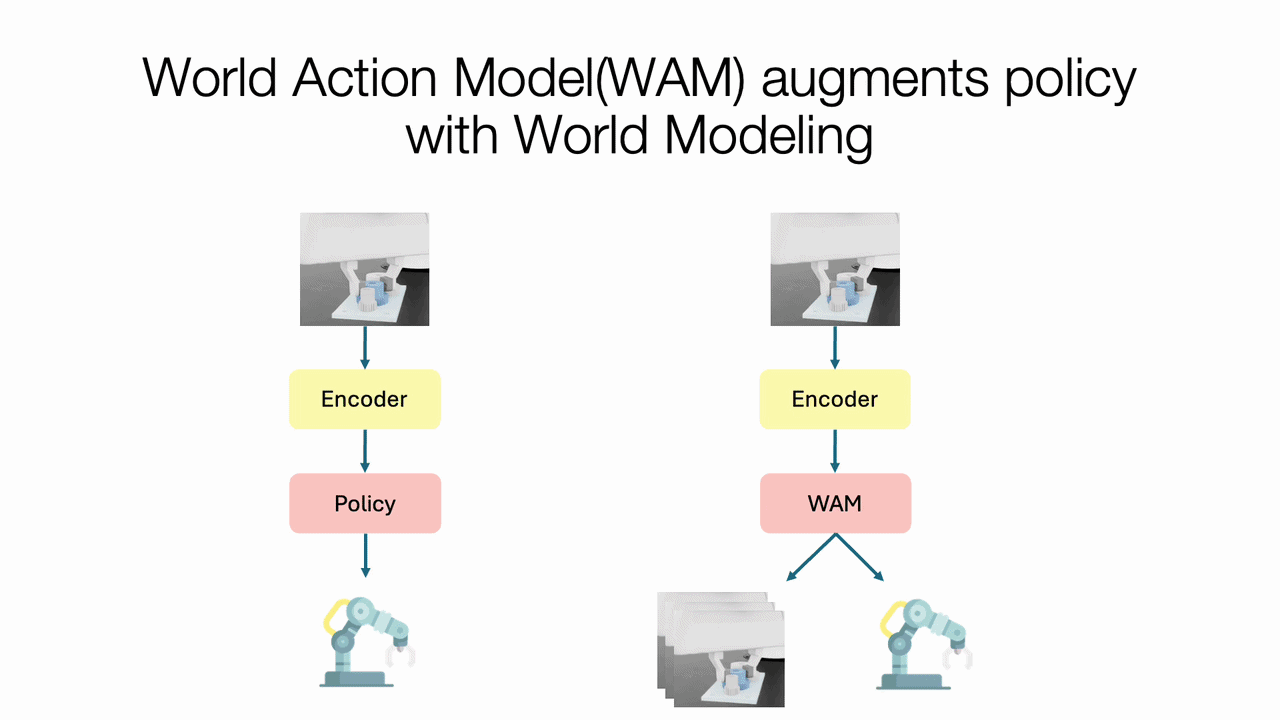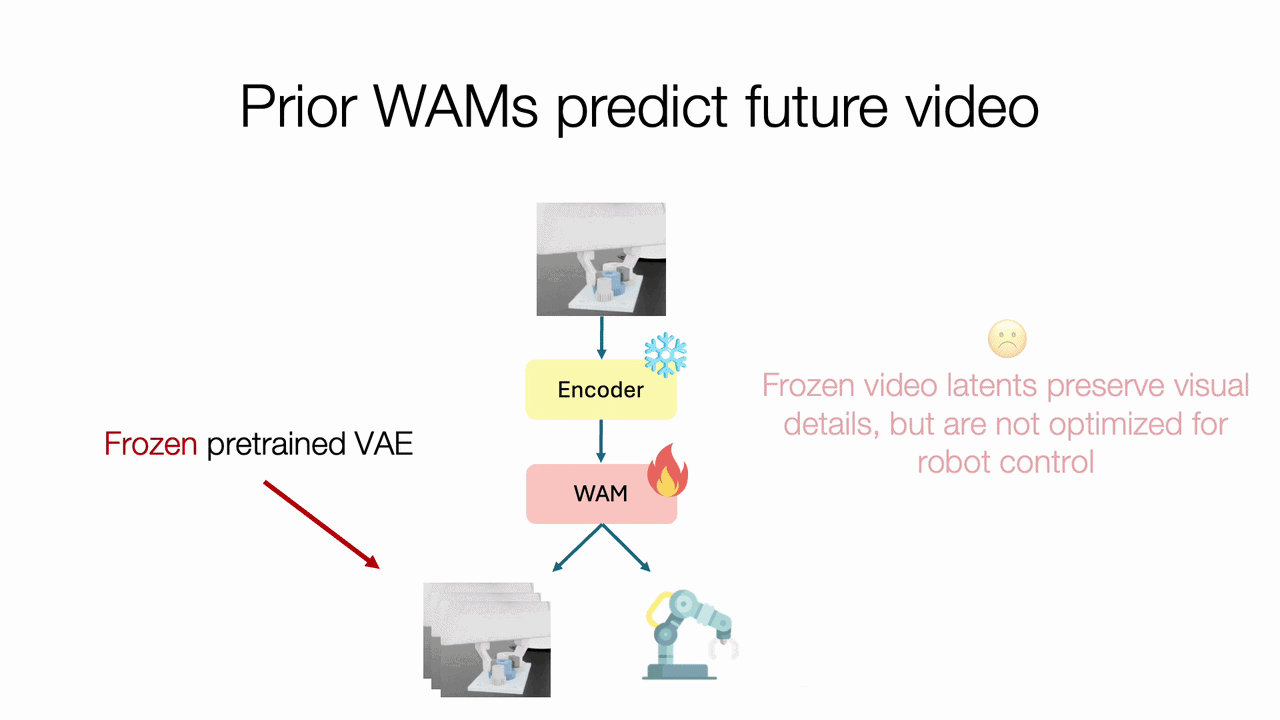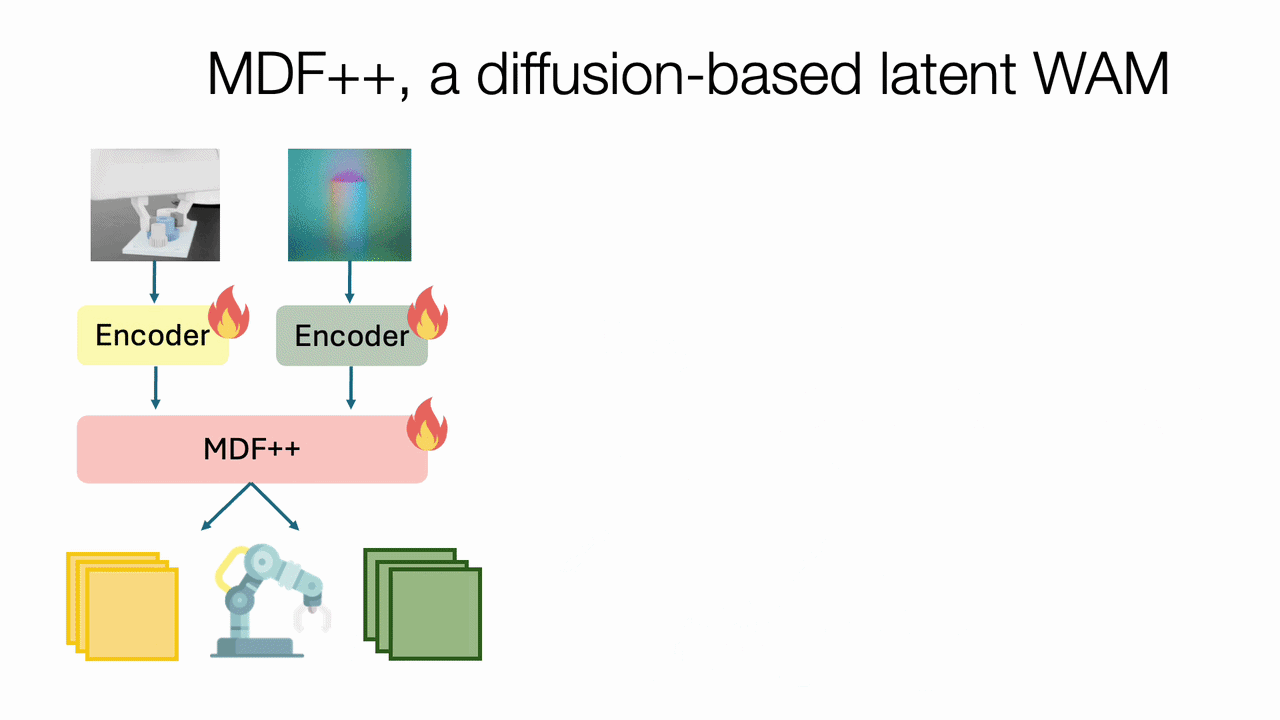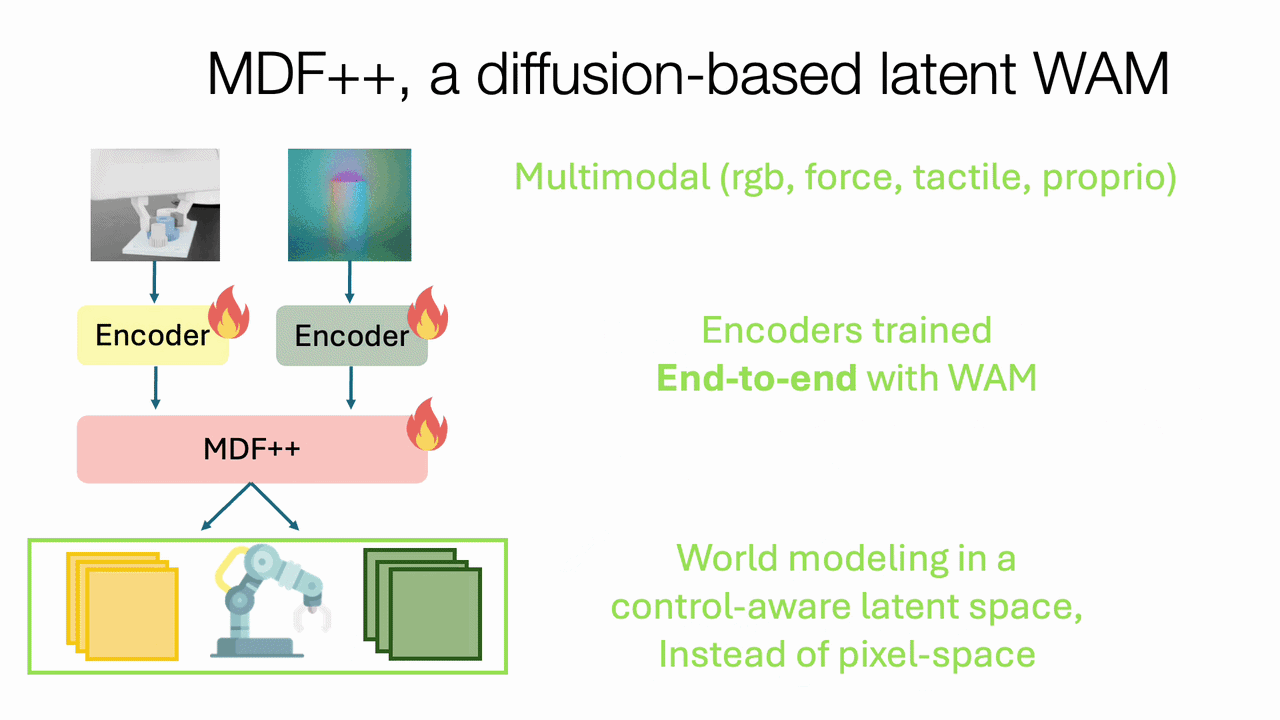
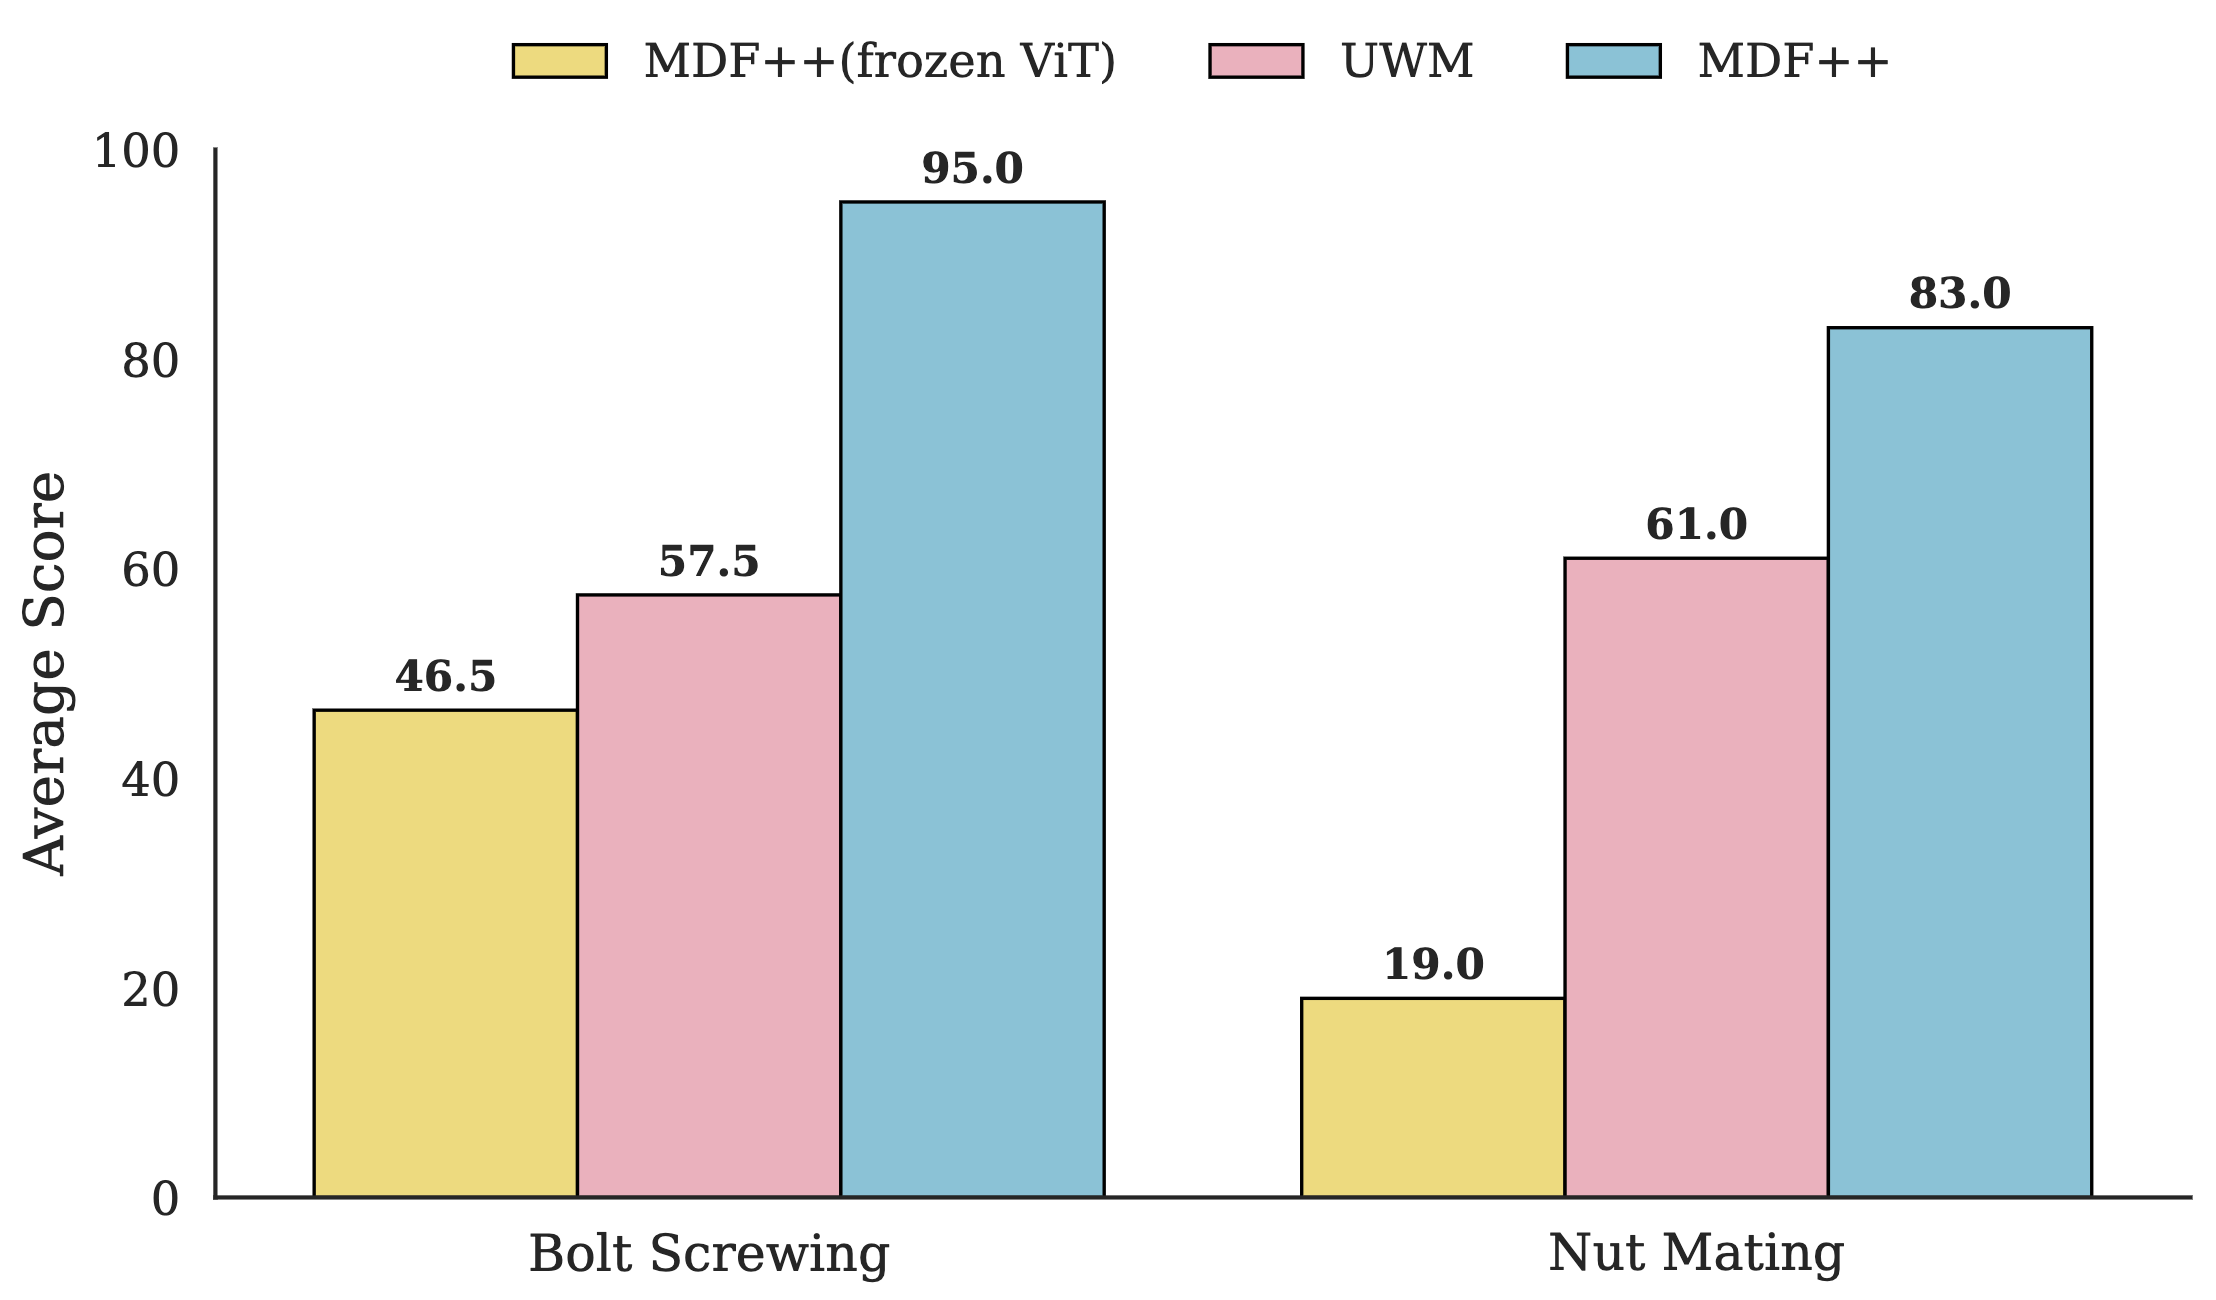
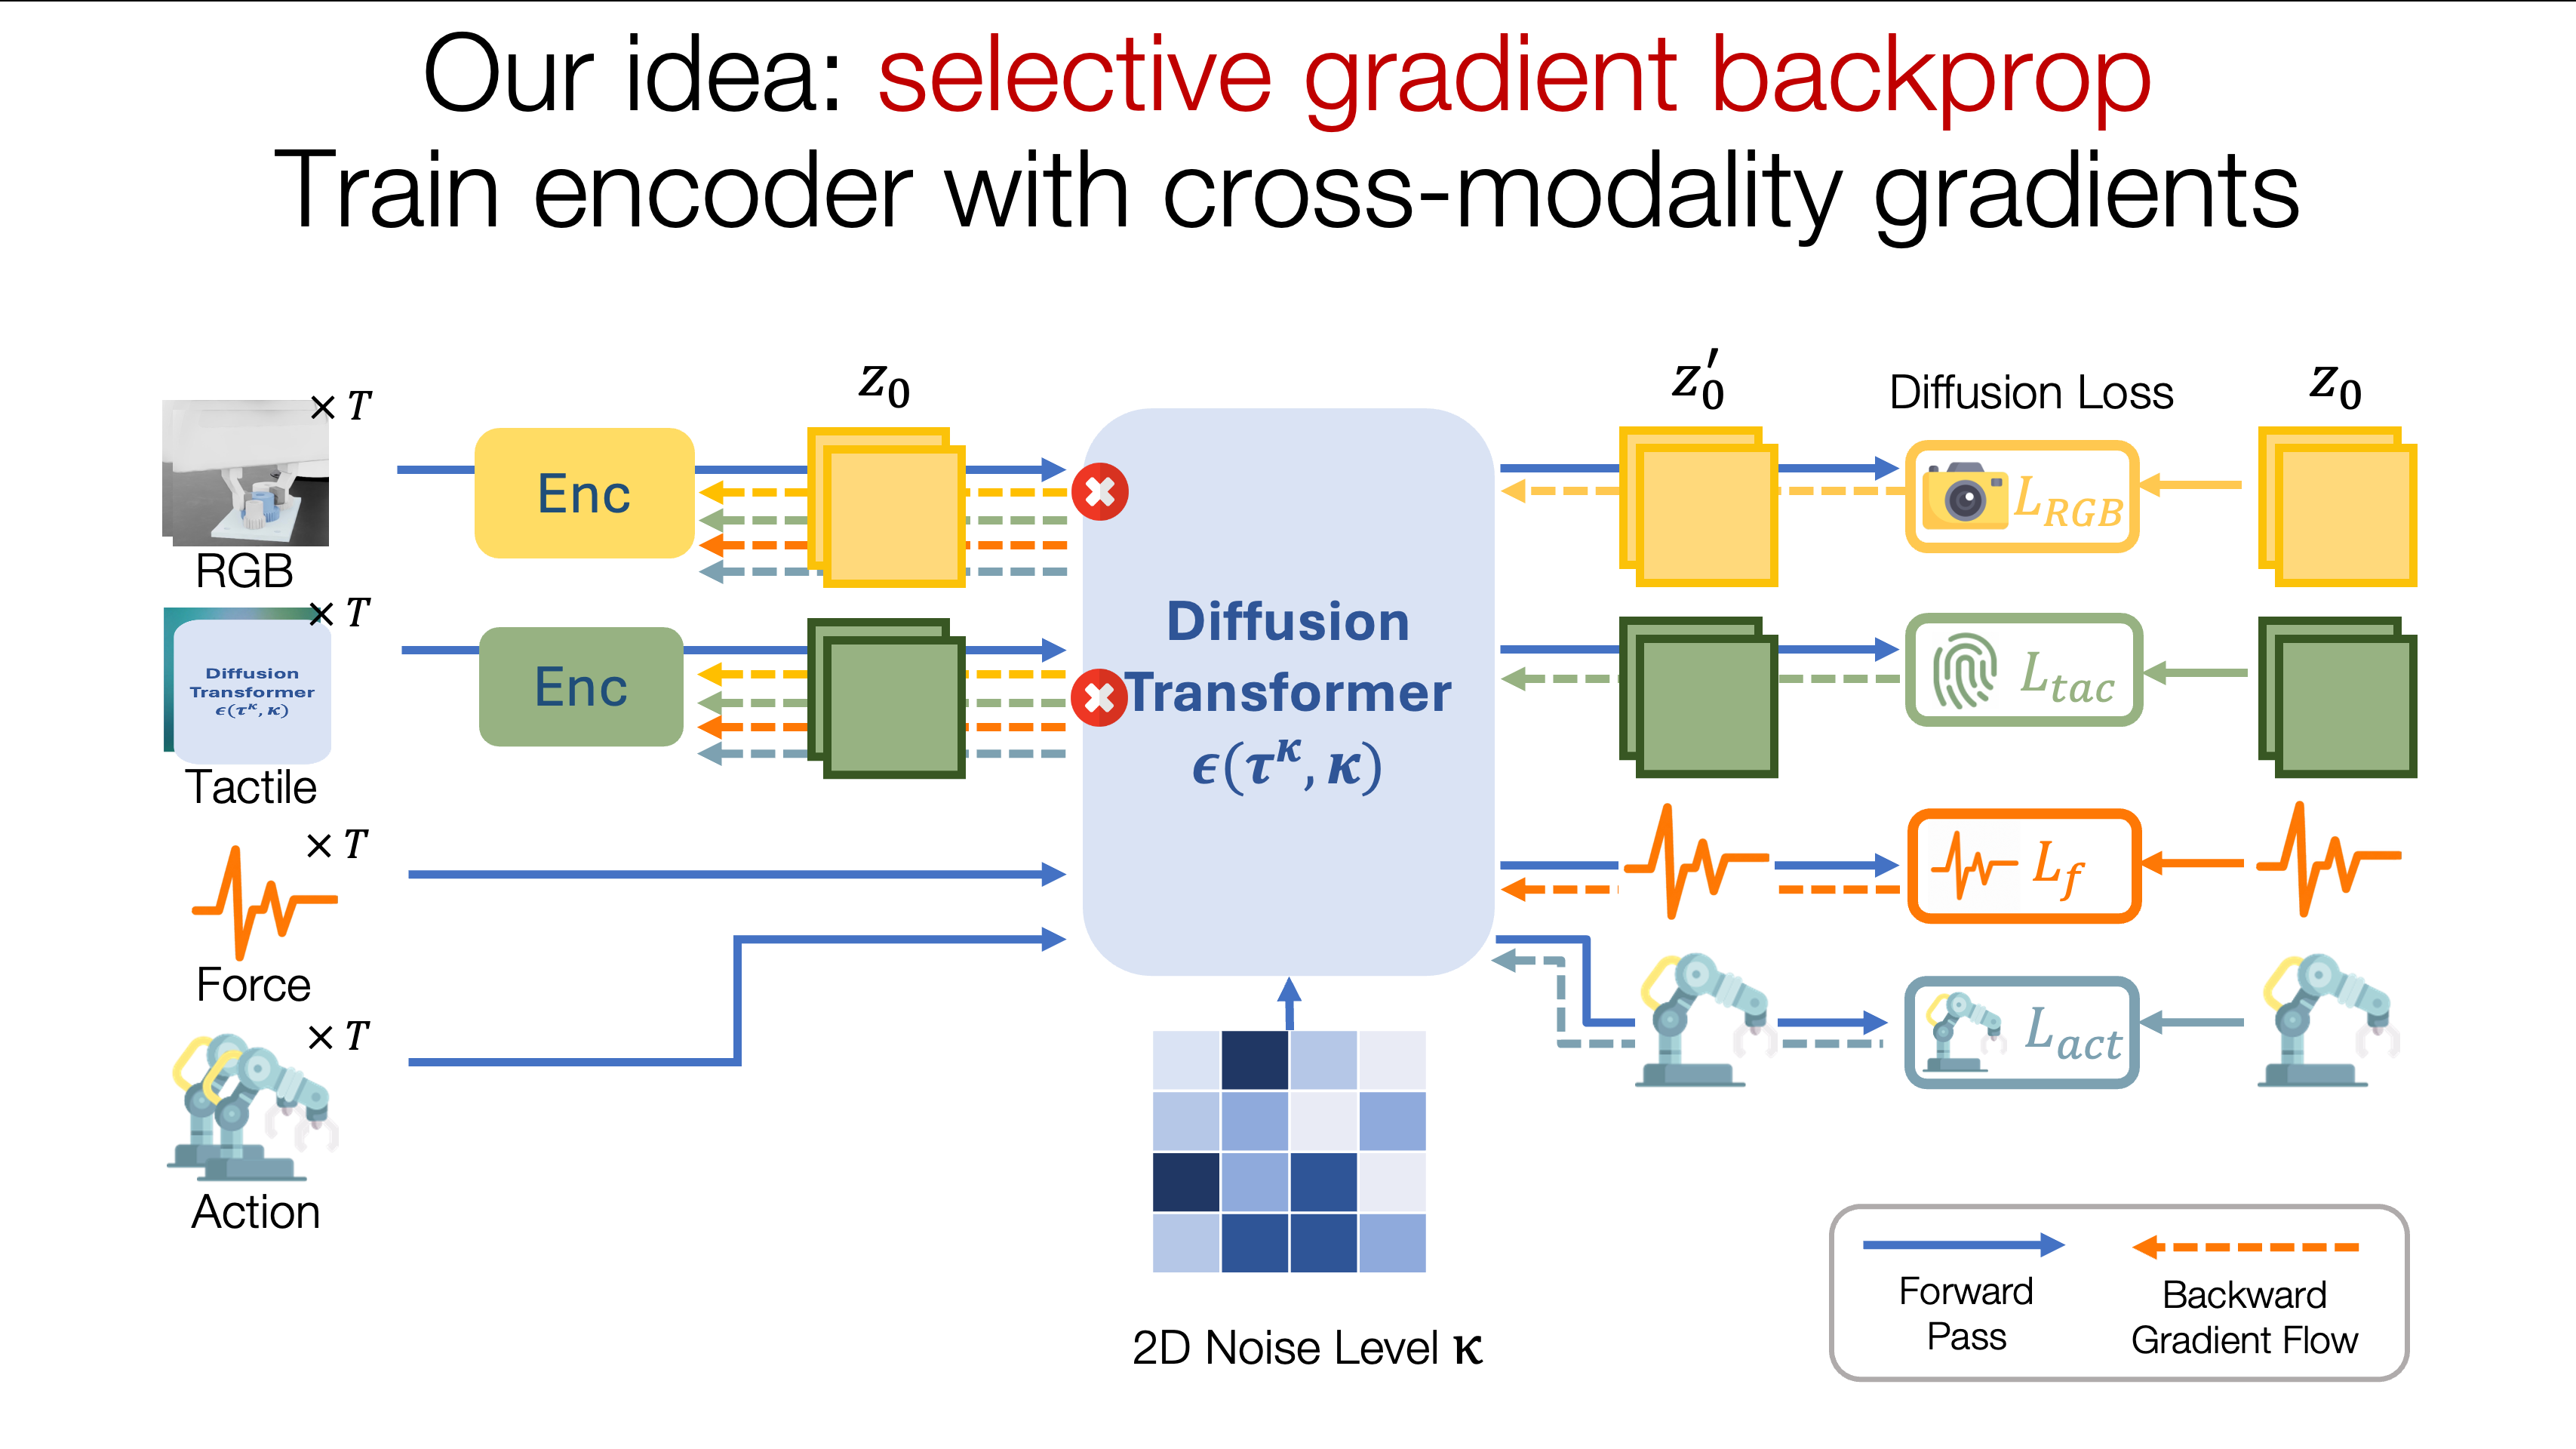
In this paper, we tackle the problem of learning physically-grounded, control-relevant representations for WAMs. We propose MDF++, a visuo-tactile world-action model that learns latent representations of multisensory observations end-to-end with a diffusion backbone. While naive joint training can lead to feature collapse, MDF++ introduces a multi-task learning strategy that leverages cross-modal correlations to learn task-relevant representations. We evaluate MDF++ on a suite of contact-rich manipulation tasks, including real-world bolt screwing and nut mating, and show that it outperforms WAMs built on frozen pretrained representations by up to 50%.